

Self-healing locators for Playwright
When a Playwright locator stops matching, healwright asks an AI model which element you meant, checks the answer against the live page, and caches it. Your test keeps going, and the next run doesn't call the model at all.
Why healwright
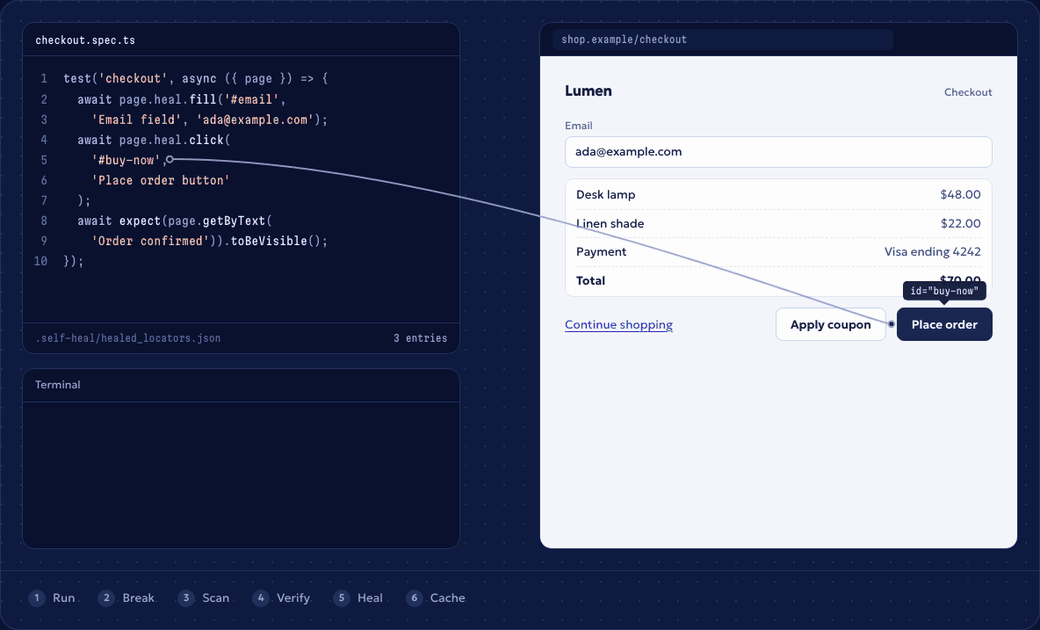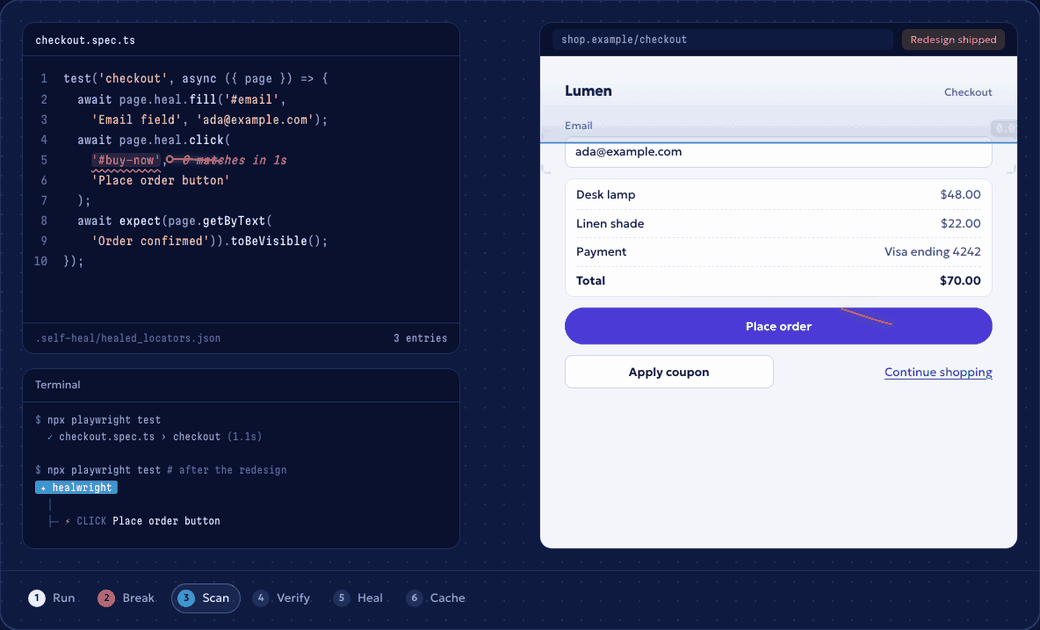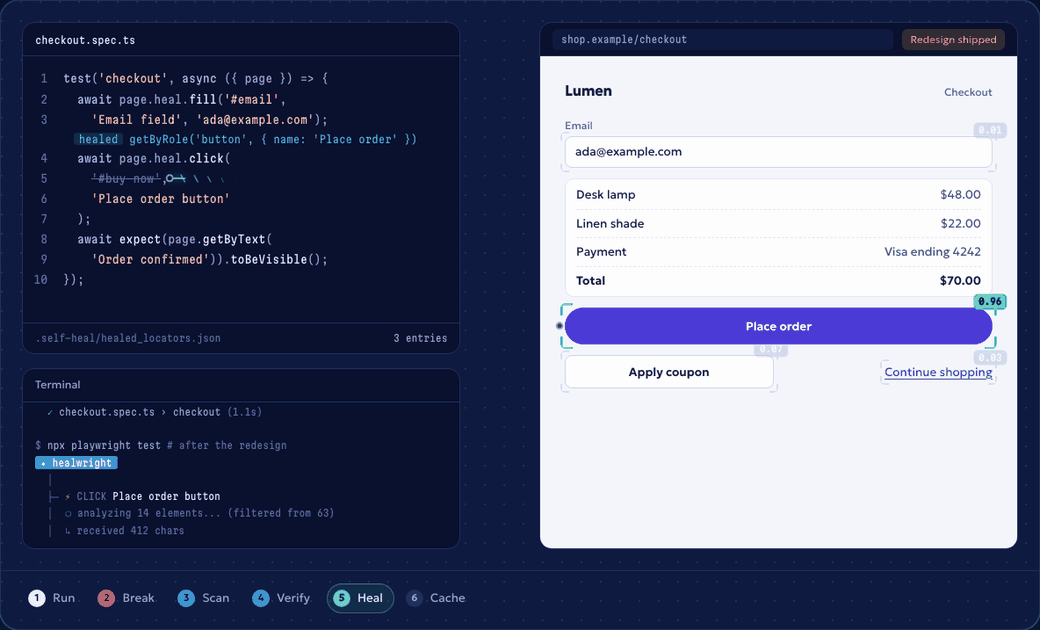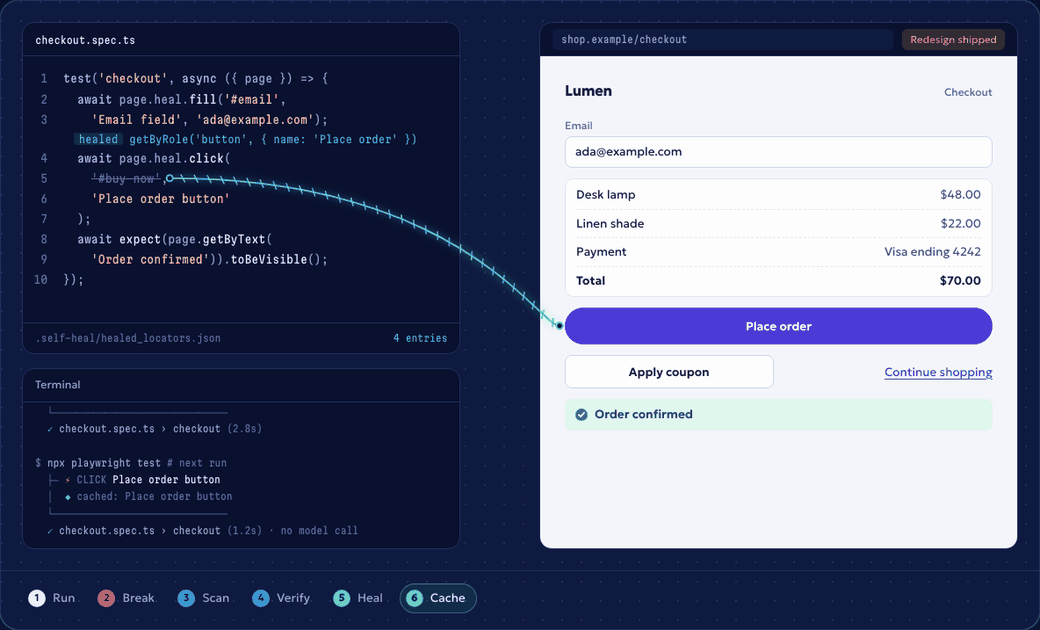
A frontend refactor renames a class or moves a button, and half your selectors stop matching. The app still works; the tests don't. Healwright repairs the locator while the test runs instead of failing the build, and tells you exactly what it changed.
- Heals at runtime. When a selector breaks, the model picks the element from a ranked list of what's actually on the page.
- Verified, not guessed. A suggestion is used only if it matches exactly one visible element with enough confidence.
- Pays once. Fixes are cached, so the model is called once per element, not once per run.
- Plain-English targets. Leave the selector empty and describe the element instead.
- Honest in CI.
minConfidence, report-only mode and a run summary keep every heal visible. - Any model. OpenAI, Anthropic Claude, Google Gemini, TypeSafe Jev, or a local Ollama model where nothing leaves your machine.
Quick start
1. Install healwright with the SDK for your provider (OpenAI is the default):
npm install healwright openai
Requires Node.js 22 and @playwright/test 1.62 or newer. Each provider's SDK is an optional peer
dependency, so you only install the one you use; the table under Providers lists them.
2. Pick a provider. Healing stays off until SELF_HEAL=1, so your suite behaves exactly as
before until you turn it on. Set these in CI, or in a .env file loaded with
import 'dotenv/config' at the top of playwright.config.ts:
SELF_HEAL=1
AI_PROVIDER=openai     # or anthropic, google, typesafe, local
AI_API_KEY=sk-...      # not needed for local (Ollama)
3. Wrap the page fixture
// fixtures.ts
import { test as base } from '@playwright/test';
import { createHealingFixture, HealPage } from 'healwright';

export const test = base.extend<{ page: HealPage }>(createHealingFixture());
export { expect } from '@playwright/test';
4. Write a test
import { test, expect } from './fixtures';

test('customer can check out', async ({ page }) => {
  await page.goto('https://shop.example/checkout');

  // No selector: the description is enough
  await page.heal.fill('', 'Email field', 'ada@example.com');

  // The selector runs first; the description takes over if it breaks
  await page.heal.click('#buy-now', 'Place order button');

  await expect(page.getByText('Order confirmed')).toBeVisible();
});
Run npx playwright test. While your selectors match, nothing changes. When one breaks, the heal
shows up in the output:
  ├─ ⚡ CLICK Place order button
  │  ⬡ analyzing 14 elements... (filtered from 63)
  │  ↳ received 412 chars
  │
  ├─ ✓ Place order button
  │  → getByRole("button", { name: "Place order" })
  │  ↑ 1180 input · 96 output · 1276 total tokens
  └──────────────────────────────
The step-by-step guide covers the same ground for every provider.
How it heals
- Your locator runs first. If the element shows up within
quickTimeout(1 second), the action runs and nothing else happens. - The cache is checked. A fix found earlier for this element on this page path is tried next.
- The page is narrowed down. Up to 1,000 interactive elements are collected and scored against your description. Only the best 40 are sent to the model, so the right one isn't lost to DOM order.
- The model suggests locators. Up to three Playwright strategies (test id, role and name, label, placeholder, text, alt text, title or CSS), each with a confidence score, as JSON that has to match a fixed schema.
- Every suggestion is checked. It must match exactly one element, that element must be
visible, and its confidence must clear
minConfidence. - The action runs and the fix is saved. The working locator goes into
.self-heal/healed_locators.json, and the heal is logged to.self-heal/heal_events.jsonlwith the model's reason and token count.
Keep healing honest
A heal that lands on the wrong element still passes. If someone deletes the checkout button and the model confidently clicks a different one, your suite goes green and nobody finds out. Three settings decide when that's acceptable.
minConfidence fails the action instead of guessing when the model isn't sure:
createHealingFixture({ minConfidence: 0.8 }) // or HEALWRIGHT_MIN_CONFIDENCE=0.8
mode: 'warn' reports what would have healed and keeps the original failure. Cached heals are
reported too, never applied, so a committed cache can't turn the audit green:
HEALWRIGHT_MODE=warn npx playwright test
getHealSummary() counts every heal in the run, so global teardown can fail the build and
list the selectors to fix:
// global-teardown.ts  (playwright.config.ts: globalTeardown: './global-teardown.ts')
import { getHealSummary } from 'healwright';

export default function () {
  const { healed, entries } = getHealSummary();
  if (healed === 0) return;

  console.error(`${healed} locator(s) needed healing. Update these selectors:`);
  for (const e of entries.filter((e) => e.outcome === 'healed')) {
    console.error(`  ${e.action} "${e.contextName}" → ${JSON.stringify(e.strategy)}`);
  }
  process.exitCode = 1;
}
Tests run in worker processes and teardown runs in the runner, so every outcome is also written to
.self-heal/heal_summary.jsonl (or HEALWRIGHT_SUMMARY_FILE), and the summary reads it from
there. Only the current run counts. If your runner stays alive between runs (UI or watch mode),
call resetHealSummary() from globalSetup to start each run at zero.
API
Methods on page.heal
Every action takes a selector or Locator (or '' to rely on the description alone) and a
description.
| Method | What it does |
|---|---|
click(target, desc, { force? }) | Click. force: true clicks controls that only appear on hover |
dblclick(target, desc) | Double-click |
fill(target, desc, value) | Type into an input or textarea |
selectOption(target, desc, value) | Choose an option in a dropdown |
check(target, desc) | Check a checkbox or radio |
uncheck(target, desc) | Uncheck a checkbox |
hover(target, desc) | Hover over an element |
focus(target, desc) | Focus an element |
locator(selector, desc) | A chainable locator with the same actions |
getLocator(selector, desc) | A real Playwright Locator, healed if needed |
heal.getLocator() for assertions
getLocator() returns a real Locator, so expect(), .nth(), .filter(), press() and
everything else Playwright offers work on it:
const badge = await page.heal.getLocator('.cart-count', 'Cart item count');
await expect(badge).toHaveText('1');

const rows = await page.heal.getLocator('.order-row', 'Order history rows');
await expect(rows).toHaveCount(3);
await rows.nth(0).click();
Chainable locators
await page.heal.locator('.new-todo', 'New todo input').fill('Buy milk');
await page.heal.locator('.toggle-all', 'Mark all as done').check();
Controls that only appear on hover
await page.heal.hover('', 'Todo item');
await page.heal.click('', 'Delete button', { force: true });   // dispatches the click directly
Without the fixture
import { withHealing } from 'healwright';

const healPage = withHealing(page, { minConfidence: 0.8 });
await healPage.heal.click('#buy-now', 'Place order button');
Providers
| Provider | AI_PROVIDER | Install | What it needs |
|---|---|---|---|
| OpenAI (default) | openai or gpt | npm install openai | AI_API_KEY |
| Anthropic Claude | anthropic or claude | npm install @anthropic-ai/sdk | AI_API_KEY |
| Google Gemini | google or gemini | npm install @google/genai | AI_API_KEY |
| TypeSafe Jev | typesafe or jev | npm install @typesafe-ai/sdk | TYPESAFE_API_KEY (or AI_API_KEY) |
| Ollama, local | local or ollama | npm install ollama | Ollama running; no key |
If the SDK for your provider isn't installed, the first heal fails with the exact npm install
command to run.
Each provider has a default model. Set AI_MODEL to choose your own.
TypeSafe Jev
Jev is a System One model: instead of writing text, it
answers typed questions with calibrated probabilities, which makes it fast and very cheap. Healwright
uses it differently from the chat models. It asks Jev which of the collected elements is the one you
described, and whether that element is on the page at all, then builds the locator in code from the
chosen element's own attributes. The answer can only ever be an element that was on the page, and
its probability becomes the confidence that minConfidence checks.
AI_PROVIDER=typesafe
TYPESAFE_API_KEY=...
On healwright's element suite (76 deliberately broken locators across buttons, links, inputs, checkboxes, ARIA widgets and hidden controls), Jev healed all 76. A heal costs about $0.0001, and the API round trip with 40 candidates took under a quarter of a second. When a description matches nothing on the page, Jev says so instead of guessing, and the error shows its best guess with the scores, so a description that doesn't match the page is easy to spot. Describe elements by what's actually there.
Custom endpoints and your own provider
AI_BASE_URL (or the baseURL option) points a built-in provider at another endpoint, such as
Azure OpenAI, OpenRouter, vLLM, LiteLLM or your own gateway:
AI_PROVIDER=openai
AI_BASE_URL=https://openrouter.ai/api/v1
AI_API_KEY=your-key
AI_MODEL=your-model
For a model healwright has no client for, implement AIProvider and pass it in. Healwright never
constructs a client of its own when you do:
import { createHealingFixture, type AIProvider } from 'healwright';

const myProvider: AIProvider = {
  name: 'openai',
  async generateHealPlan({ systemPrompt, userContent, jsonSchema }) {
    const plan = await callYourModel(systemPrompt, userContent, jsonSchema);
    return { plan, tokenUsage: null };
  },
};

export const test = base.extend<{ page: HealPage }>(
  createHealingFixture({ aiProvider: myProvider })
);
Local LLM with Ollama
Run healing entirely on your machine with Ollama: no API keys, no cloud calls, no usage fees.
ollama pull gemma3:4b                                # 1. pull a model
AI_PROVIDER=local SELF_HEAL=1 npx playwright test    # 2. point healwright at it
| Model | Size | Tested | Good for |
|---|---|---|---|
llama3.2:3b | 2.0 GB | 5/5 pass | The best overall choice: fast, accurate and small |
mistral | 4.1 GB | 5/5 pass | The most accurate, and the slowest (about 1.4 min per run) |
gemma3:4b (default) | 3.3 GB | 4/5 pass | Faster than mistral (about 53 s), slightly less accurate |
Small models (1B to 4B) can struggle when several elements look alike, such as a row of
checkboxes. If accuracy matters more than speed, use mistral or a larger model. Any model from
the Ollama library works through AI_MODEL, and OLLAMA_HOST
points at an Ollama server on another machine.
Configuration
Fixture options
Pass these to createHealingFixture() or withHealing(page, options).
| Option | Default | What it does |
|---|---|---|
enabled | SELF_HEAL=1 | Turns healing on |
mode | 'heal' | 'heal', 'warn' (report only) or 'off' |
provider | 'openai' | openai, anthropic, google, typesafe or local |
model | Provider default | Overrides the model |
apiKey | AI_API_KEY | The provider's API key |
baseURL | AI_BASE_URL | Sends requests to another endpoint |
aiProvider | None | Your own provider, used instead of the built-in clients |
minConfidence | 0 | Rejects heals scored below this (0 to 1). 0 accepts any |
quickTimeout | 1000 | Milliseconds your own selector gets before healing starts |
timeout | 5000 | Milliseconds for the healed locator and the action |
maxCandidates | 40 | How many ranked elements are sent to the model |
maxAiTries | 4 | How many suggested strategies are checked before giving up |
cacheFile | .self-heal/healed_locators.json | Where heals are cached |
reportFile | .self-heal/heal_events.jsonl | Where heal attempts are logged |
logLevel | 'info' | 'info', 'error' or 'silent' |
quickTimeout is short on purpose: a broken selector should fail fast. If parts of your app
legitimately render slowly, raise it. Too low a value turns "slow" into "broken" and spends a model
call on it.
Environment variables
| Variable | What it does |
|---|---|
SELF_HEAL | Set to 1 to turn healing on |
AI_PROVIDER | openai/gpt, anthropic/claude, google/gemini, typesafe/jev, or local/ollama |
AI_API_KEY | The provider's API key. Not needed for Ollama |
TYPESAFE_API_KEY | TypeSafe's API key, read before AI_API_KEY when the provider is TypeSafe |
AI_MODEL | Overrides the provider's default model |
AI_BASE_URL | Sends requests to another endpoint |
OLLAMA_HOST | Your Ollama server. Defaults to http://127.0.0.1:11434 |
HEALWRIGHT_MODE | heal, warn or off |
HEALWRIGHT_MIN_CONFIDENCE | Same as minConfidence |
HEALWRIGHT_LOG | info, error or silent |
HEALWRIGHT_SUMMARY_FILE | Moves the summary file from .self-heal/heal_summary.jsonl |
Cache and logs
File in .self-heal/ | What's in it | In git? |
|---|---|---|
healed_locators.json | Every heal that worked, by action, page path and description | Commit it to share heals with your team and CI |
heal_events.jsonl | One line per heal attempt: the model's reason, confidence and token count | Ignore |
heal_summary.jsonl | The outcomes getHealSummary() reads at the end of a run | Ignore |
.self-heal/heal_events.jsonl
.self-heal/heal_summary.jsonl
.self-heal/*.lock
.self-heal/*.tmp
# Or keep heals local to each machine instead:
# .self-heal/
Keeping token use low
- Compact candidates. Only attributes that have a value are sent, with short keys (
tidfor a test id,txtfor text). - Hidden elements are flagged, not dropped. Real apps hide the element you want (styled
checkboxes, hover-only buttons), so hidden elements are sent marked
hid: true. - Rank, then cut. Everything is scored by keyword match, element type, ARIA role and test id
before the top
maxCandidatesare sent. - Short answers. The model returns at most three strategies.
Fewer candidates means fewer tokens and faster answers. The default of 40 suits most pages:
createHealingFixture({ maxCandidates: 15 })   // simple pages: cheaper and faster
createHealingFixture({ maxCandidates: 80 })   // dense pages: better accuracy
Token usage is printed for every heal and recorded in heal_events.jsonl for cost tracking.
Privacy and security
When healing runs, healwright sends a structured list of candidate elements (tag names, roles, ARIA
labels, text, test ids and similar attributes) and the page URL to your AI provider. No screenshots
and no full page HTML are sent. Hidden elements are included, flagged hid: true, because the
element you want is often deliberately hidden.
If the DOM can contain sensitive data such as personal or financial details or internal URLs, you can:
- Use a local model with
AI_PROVIDER=local, so nothing leaves your machine. - Use your own endpoint with
AI_BASE_URL, or your own provider withaiProvider, for full control over what is sent. - Limit healing to non-production environments.
- Review what was sent in
.self-heal/heal_events.jsonl.
Known limitations
- Cloud providers need an API key and network access; a local model needs neither.
- A heal adds model latency, usually 1 to 2 seconds with a cloud model and more on slow local hardware.
- Only the main frame is searched, so elements inside iframes aren't candidates yet. Open shadow roots are searched.
force: trueclicks dispatch the event directly, without pointer coordinates.- The cache is shared across parallel workers through a lock file. It's best effort, not a database.
Try it without your own project
The test-published branch is a
standalone project that installs the published package and runs tests with deliberately broken
selectors:
git clone -b test-published https://github.com/amrsa1/healwright.git healwright-demo
cd healwright-demo
npm install && npx playwright install chromium
cp example.env .env   # add your API key
npm test
It includes a broken-locator test, where #wrong-todo-input heals to the real input, and a
description-only test with no selector at all. There's also a
demo video of a live session.
Development
npm install
npm run typecheck && npm run lint && npm run test:unit
npm run build
npm run test:offline   # real-browser tests with a scripted provider, no API key
SELF_HEAL=1 npm test   # end-to-end tests, needs an API key
Releasing
Releases follow the version in package.json. Bump it in your pull request (npm version minor --no-git-tag-version) and add a matching ## [x.y.z] section to CHANGELOG.md; when the pull
request merges, the Release workflow runs the checks, publishes to npm with provenance, tags the
commit and creates the GitHub Release from that section. You can also run the workflow by hand with
a patch, minor or major bump. A failed run can be re-run: it skips whatever is already done.
Issues and pull requests are welcome on GitHub. If healwright saves you a broken build, a star on the repo helps other people find it.
License
MIT © Amr Salem

